Bounding boxes
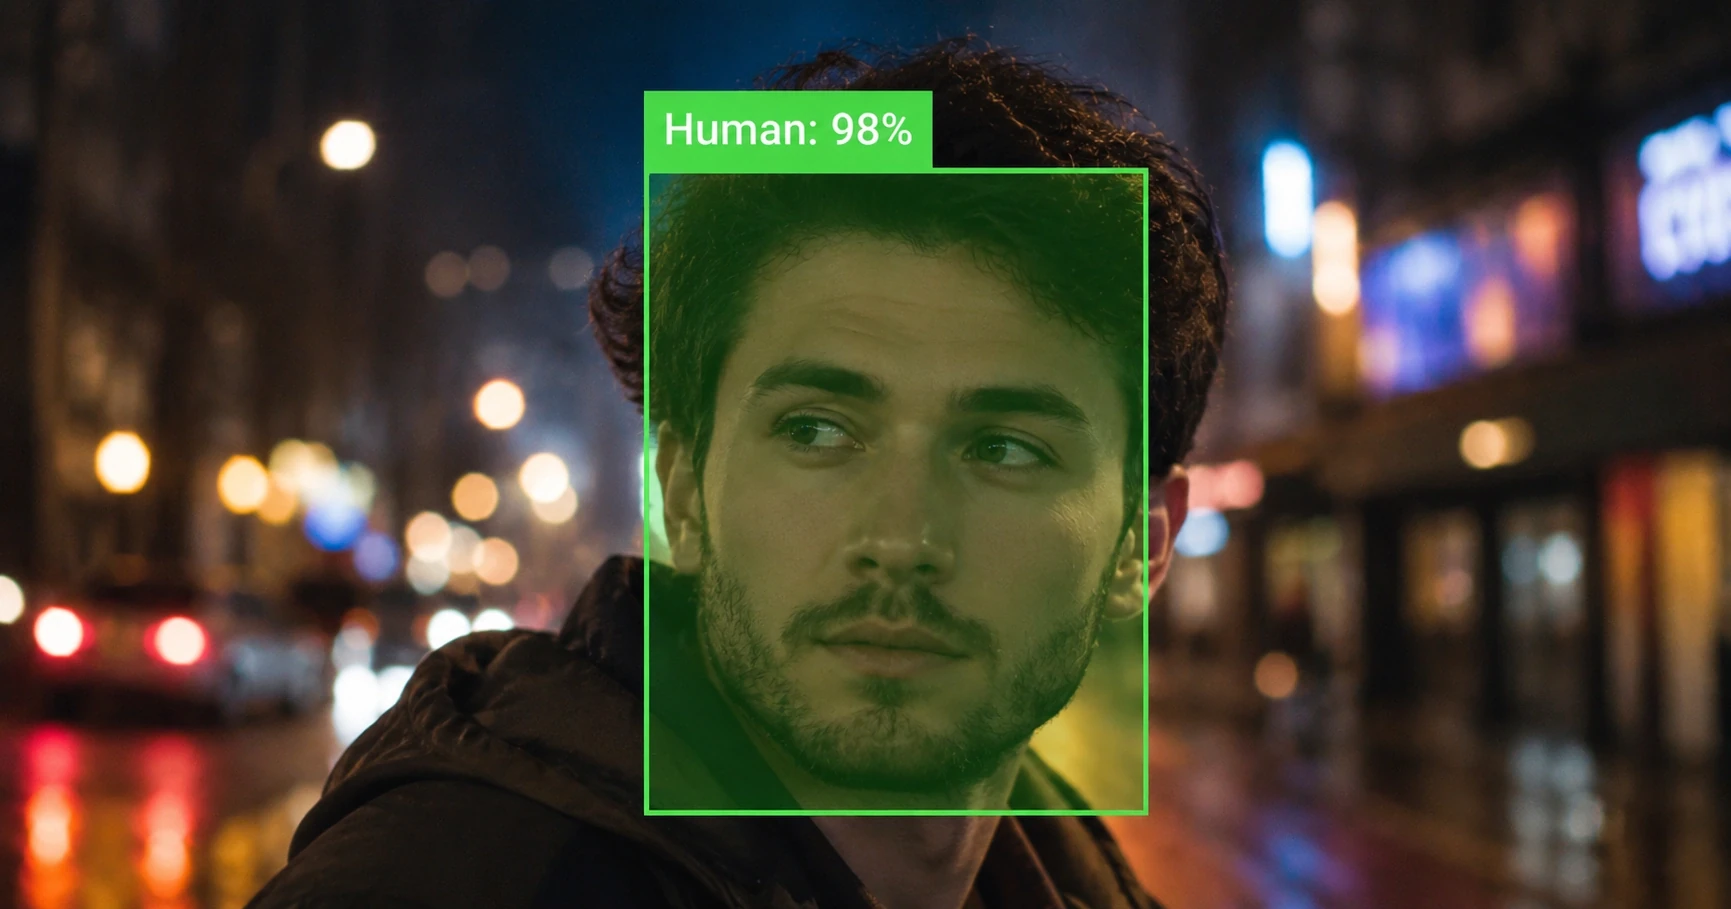
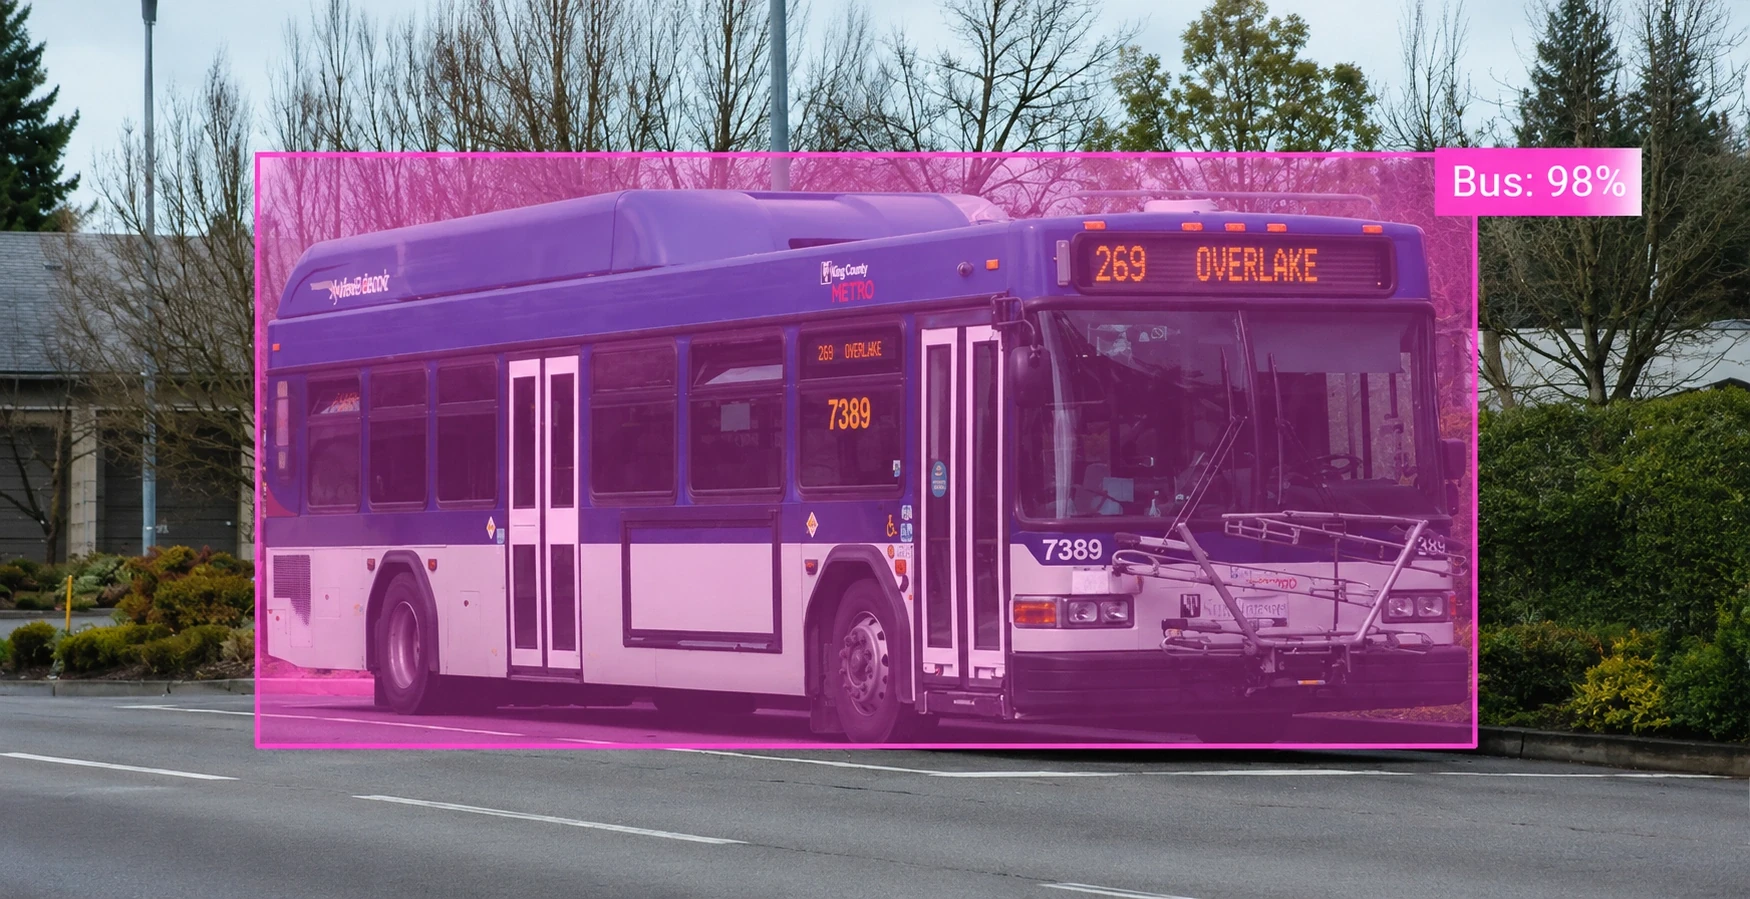
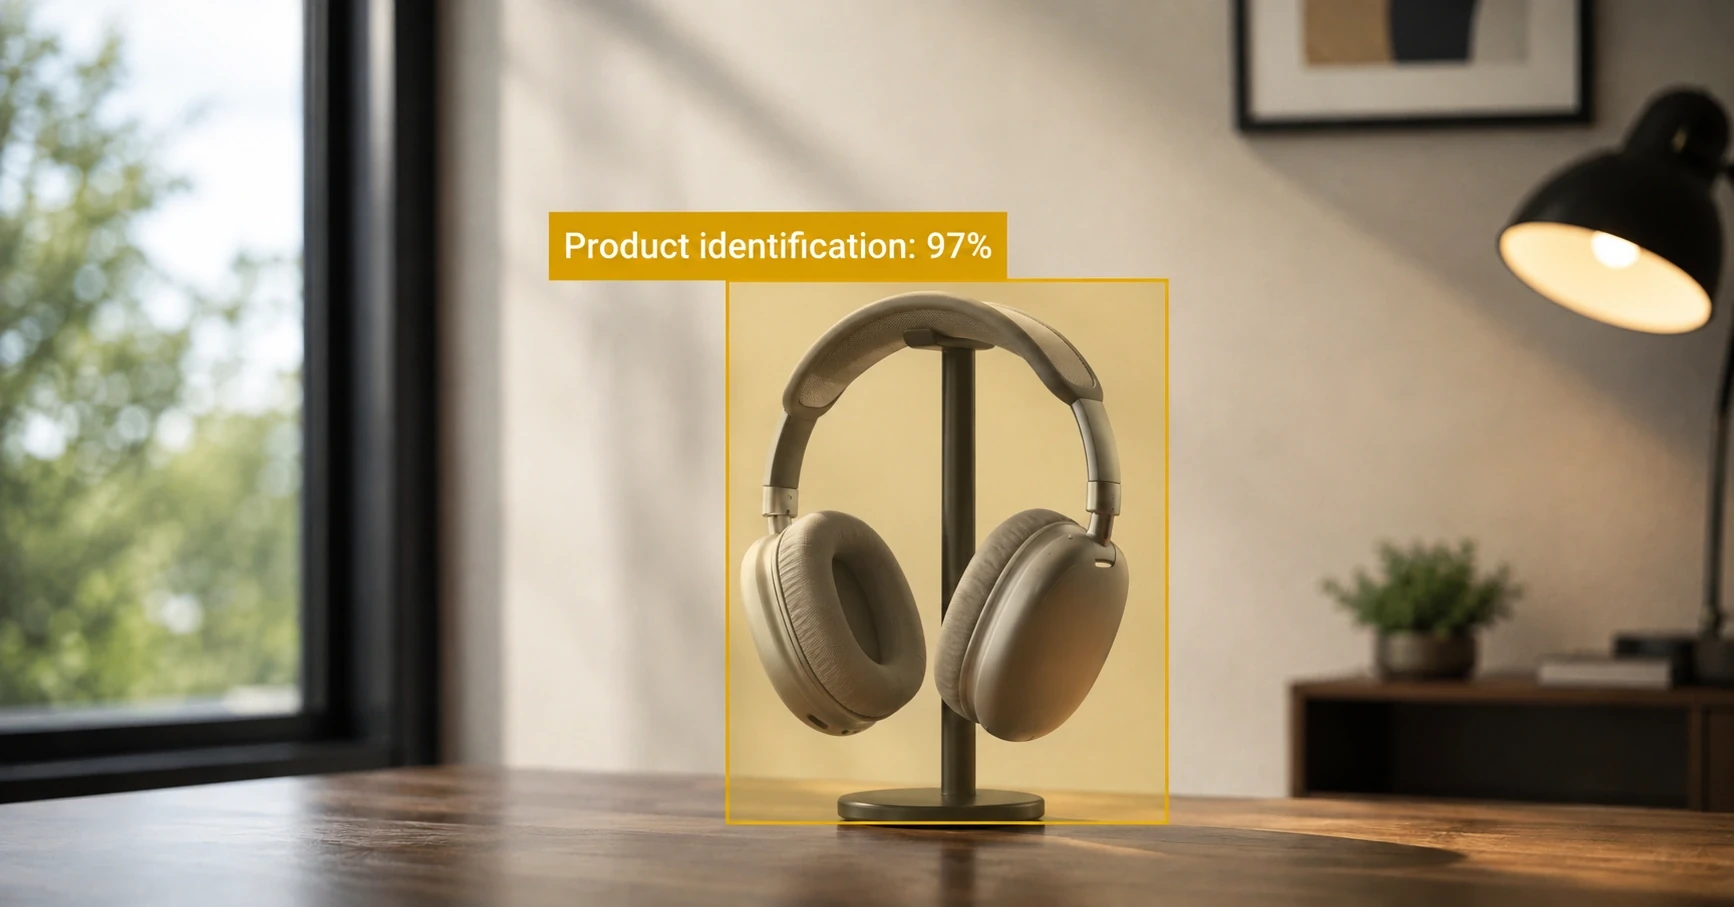
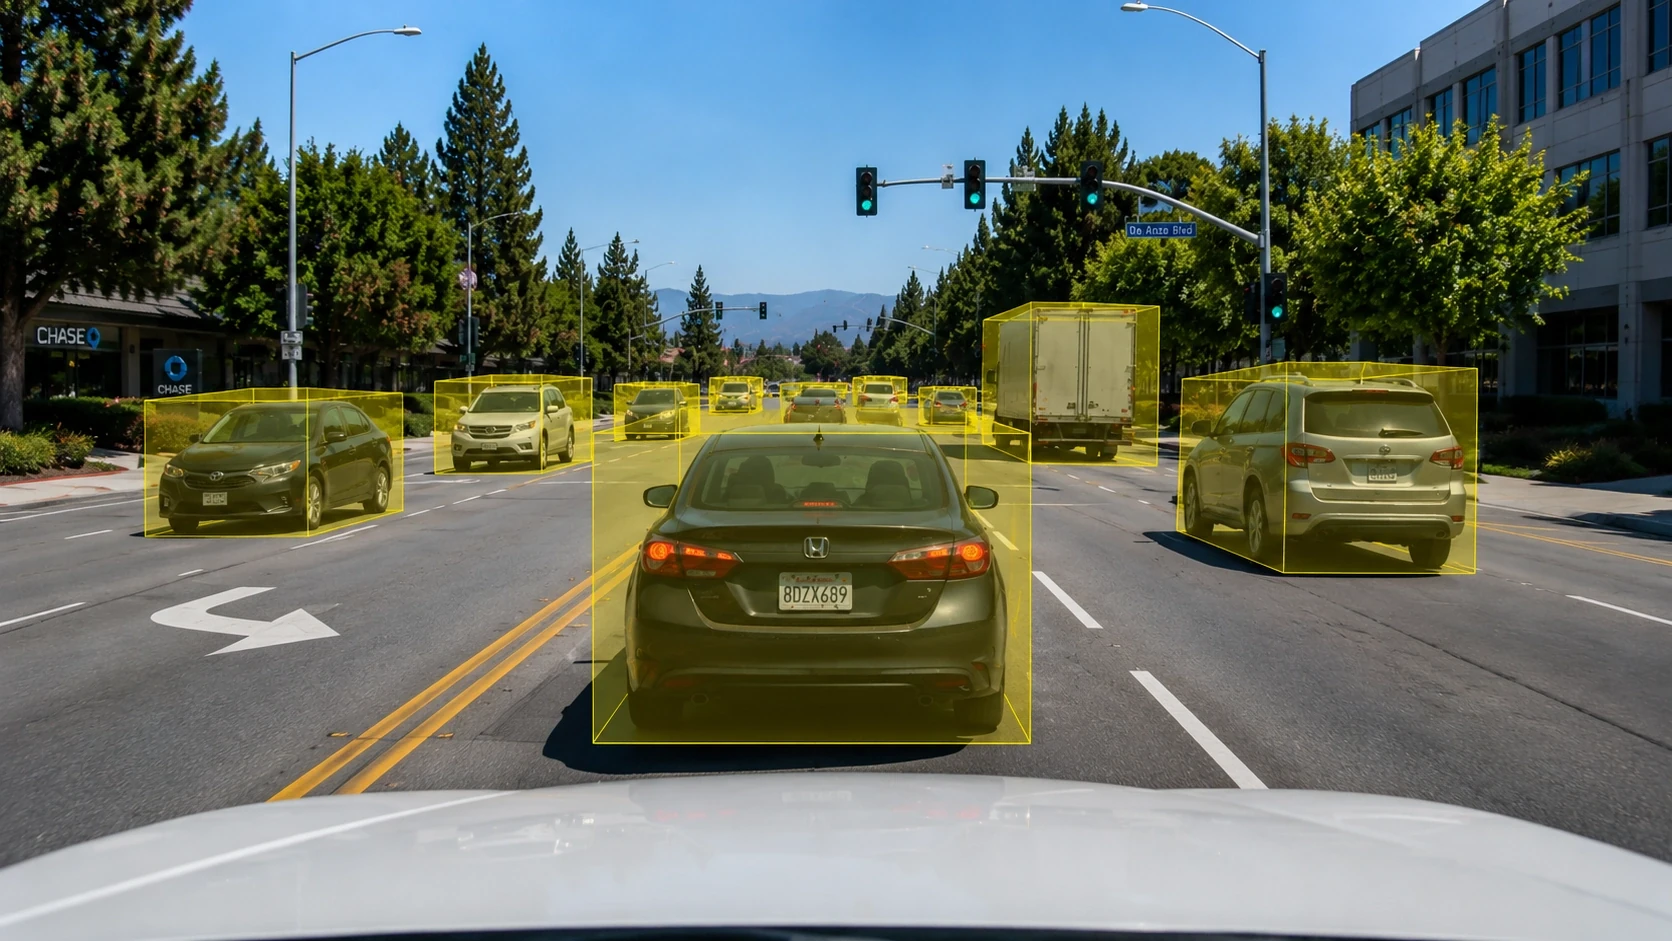
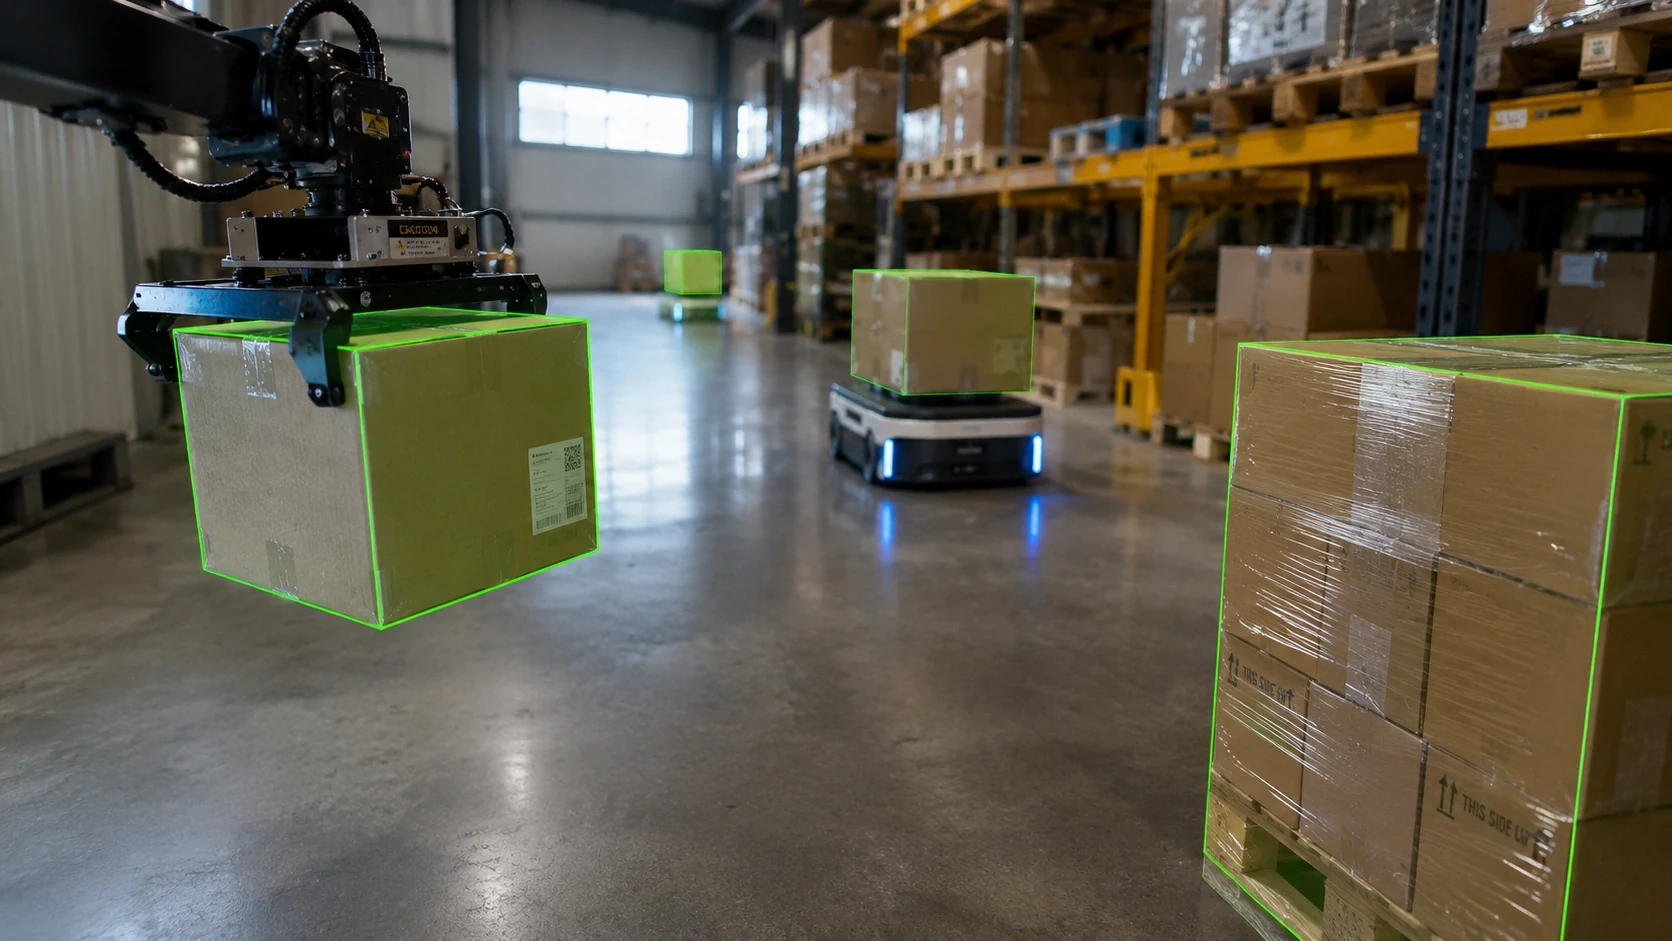
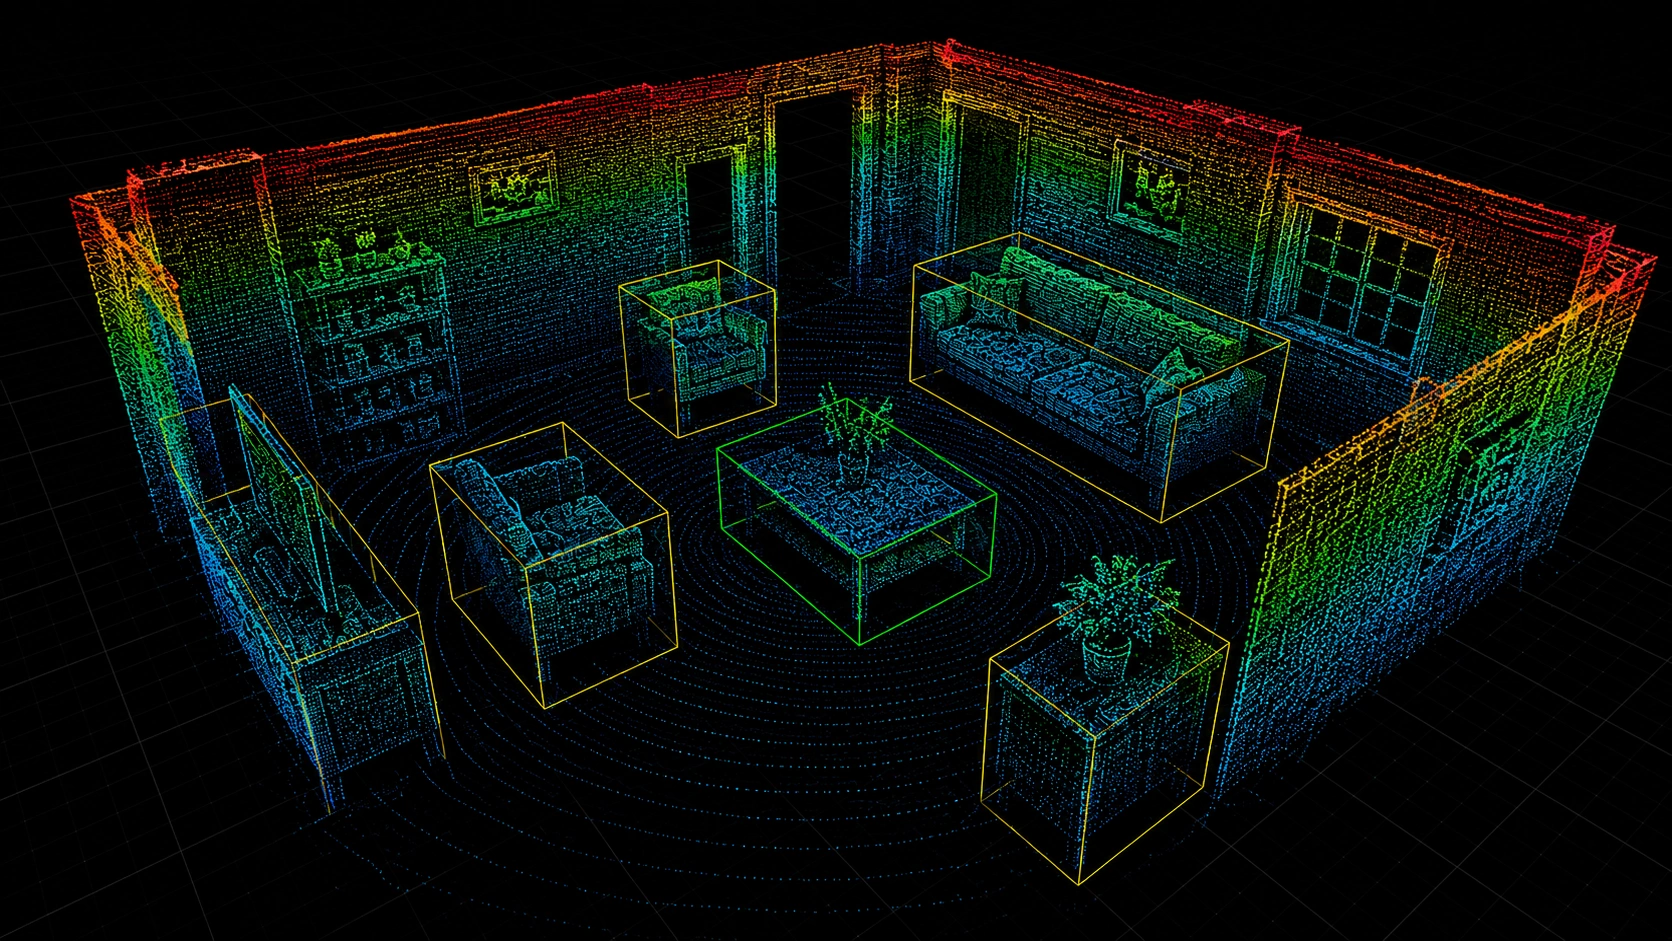
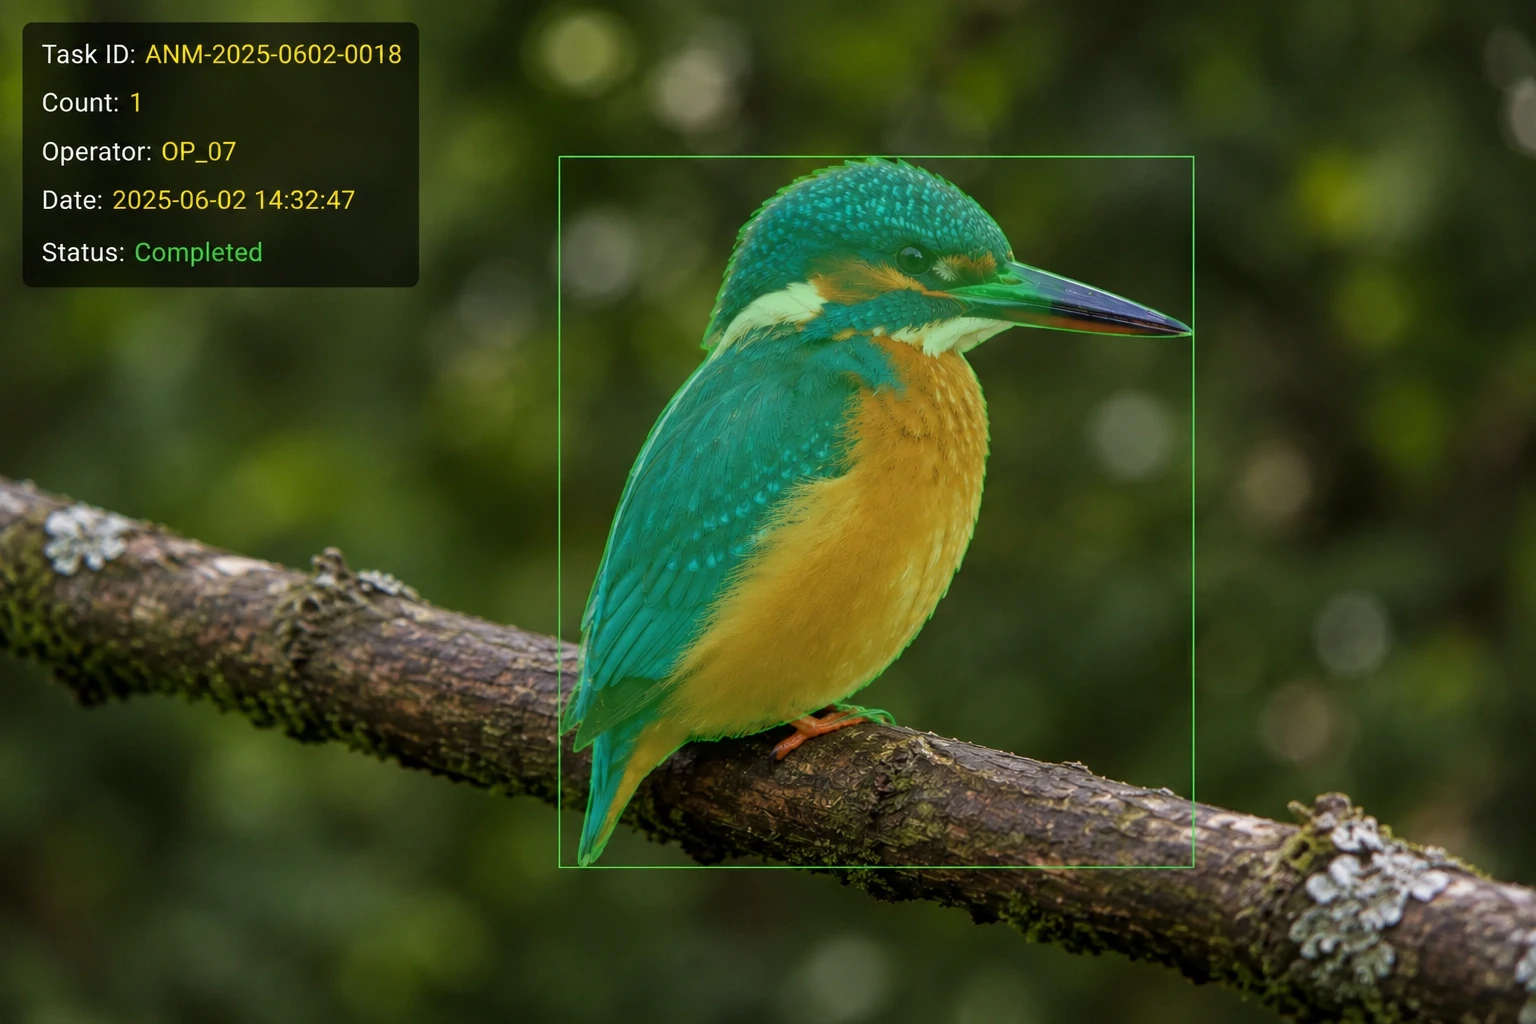
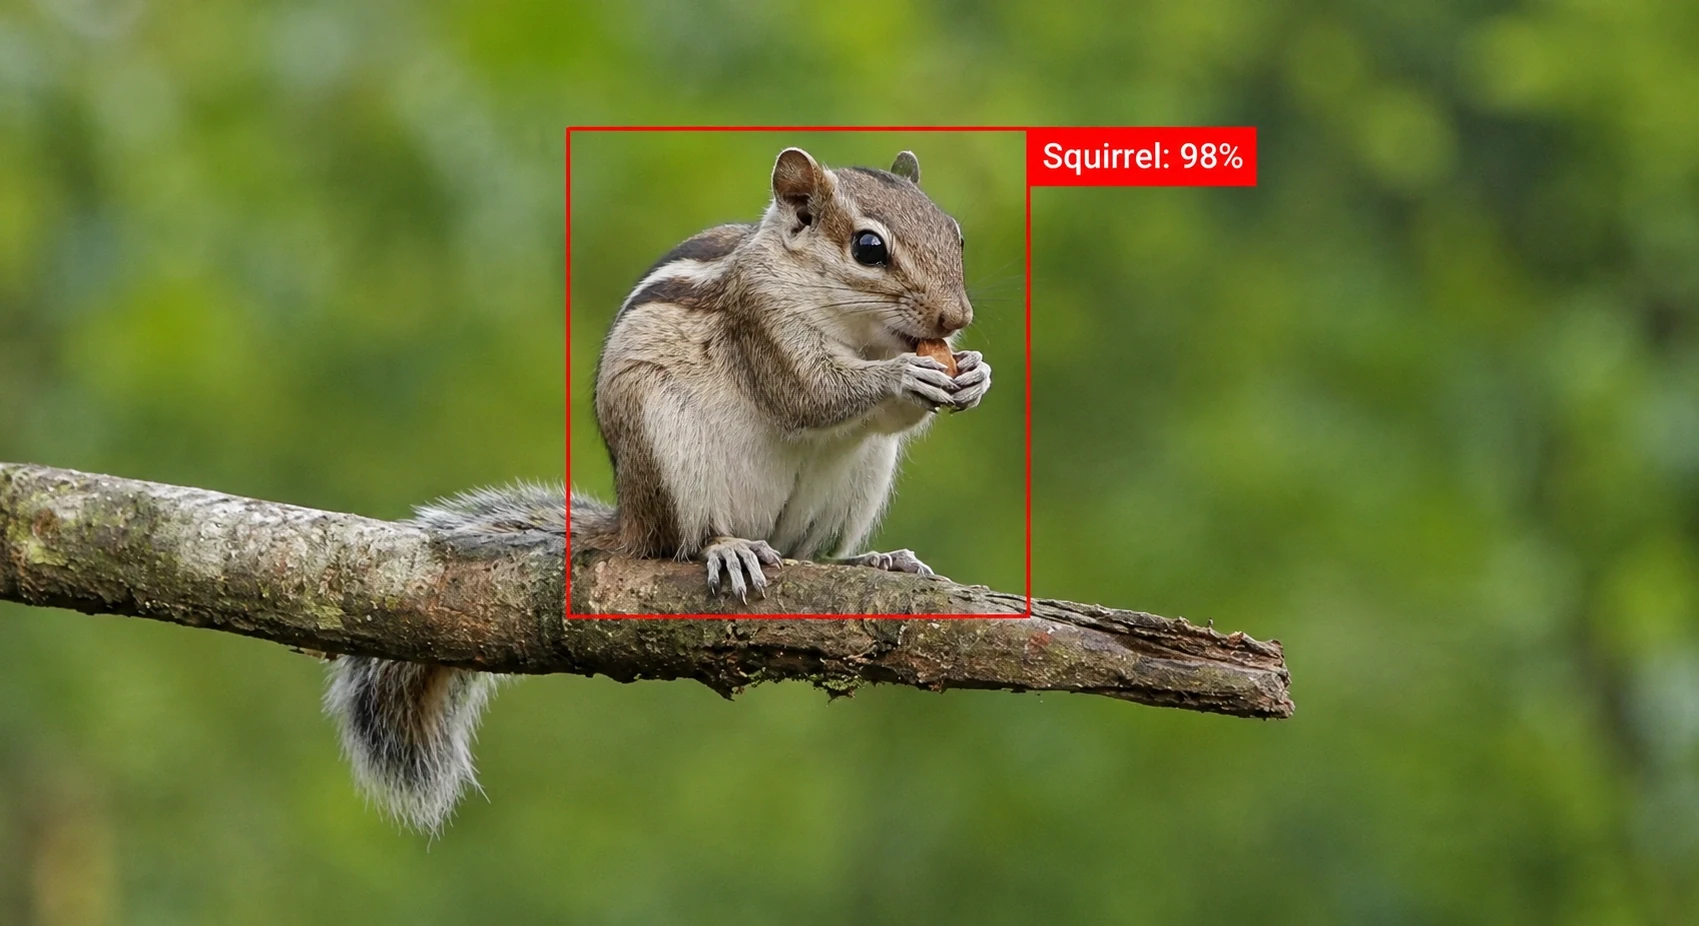
Localizing and classifying objects quickly with tight rectangular boundaries, essential for object detection and tracking.
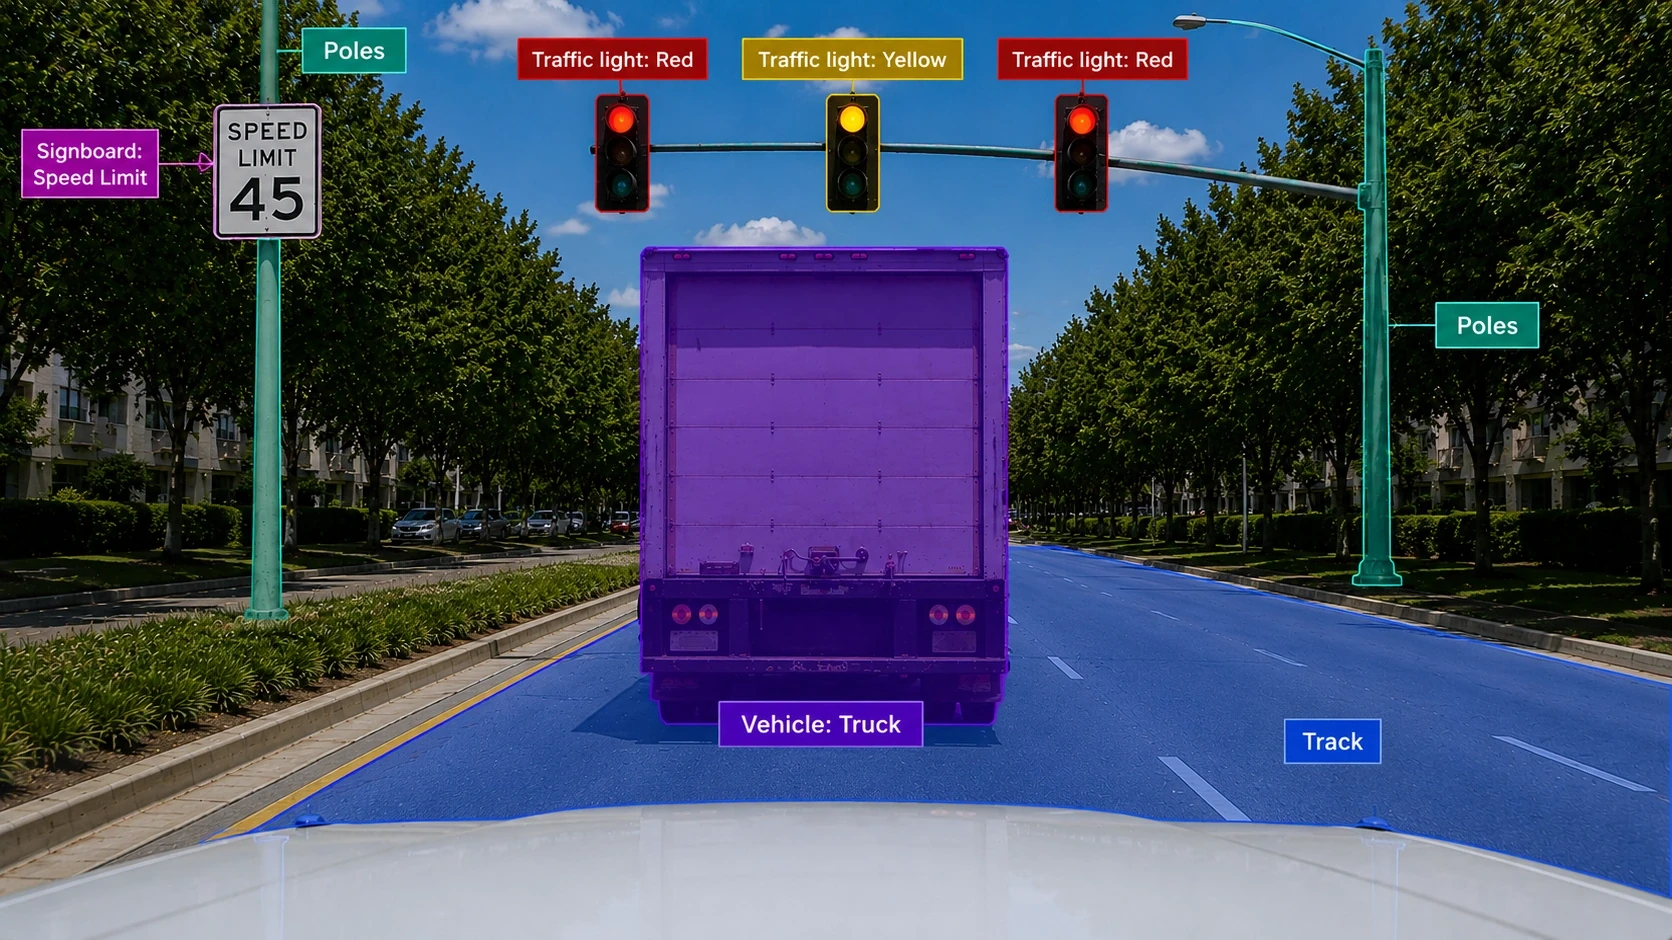
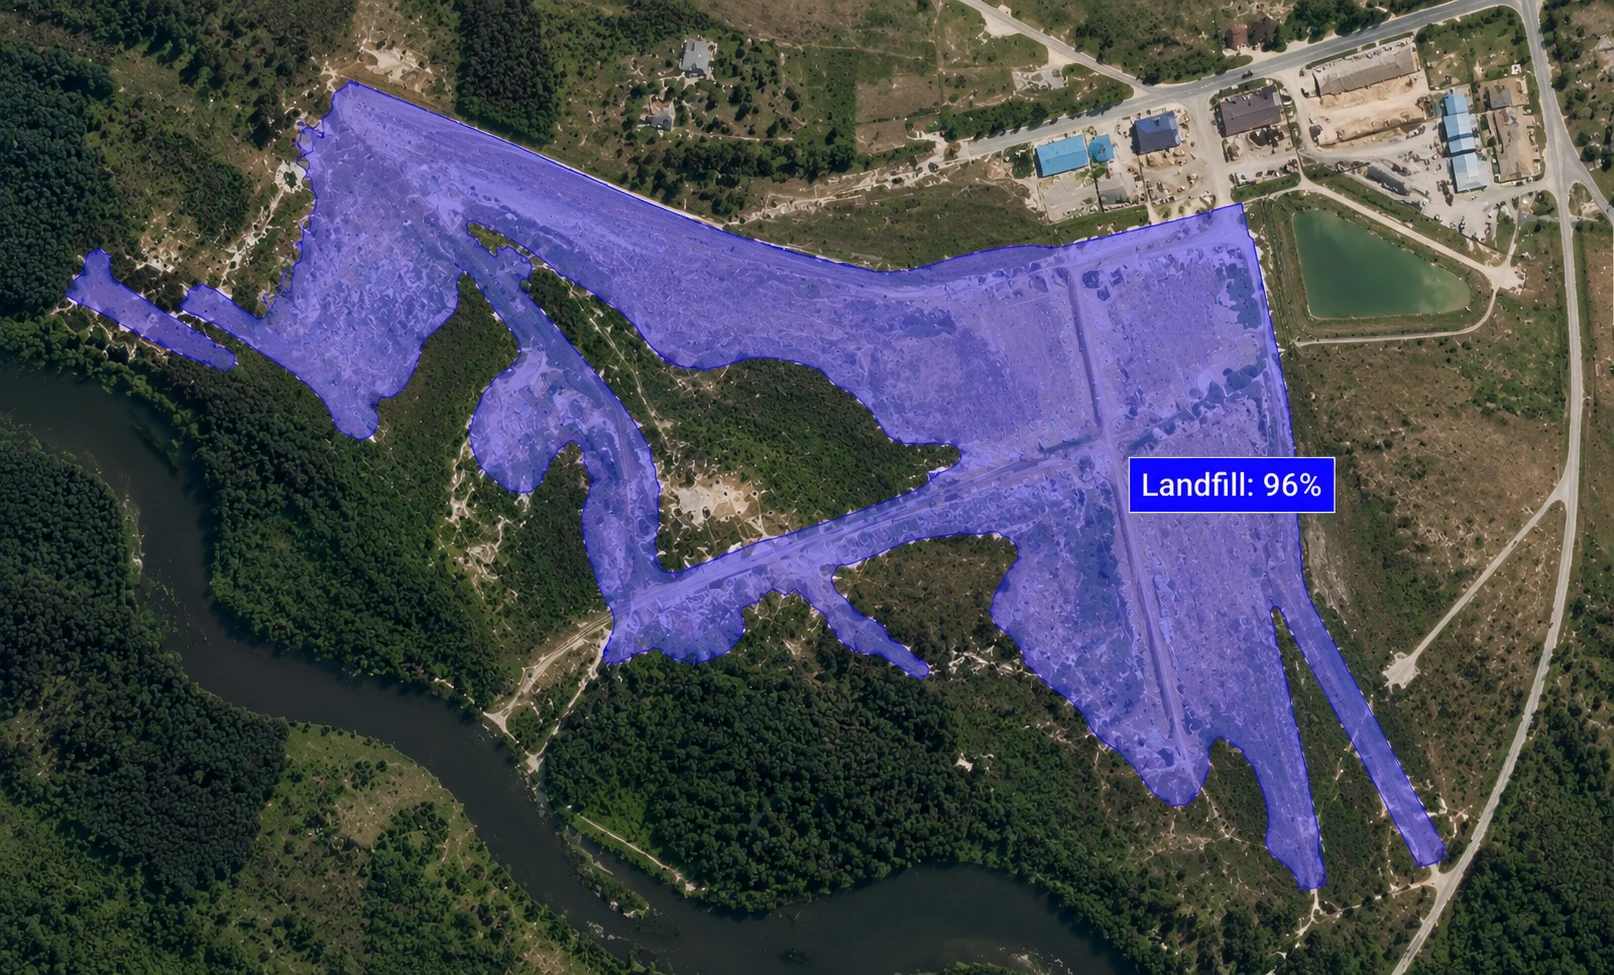
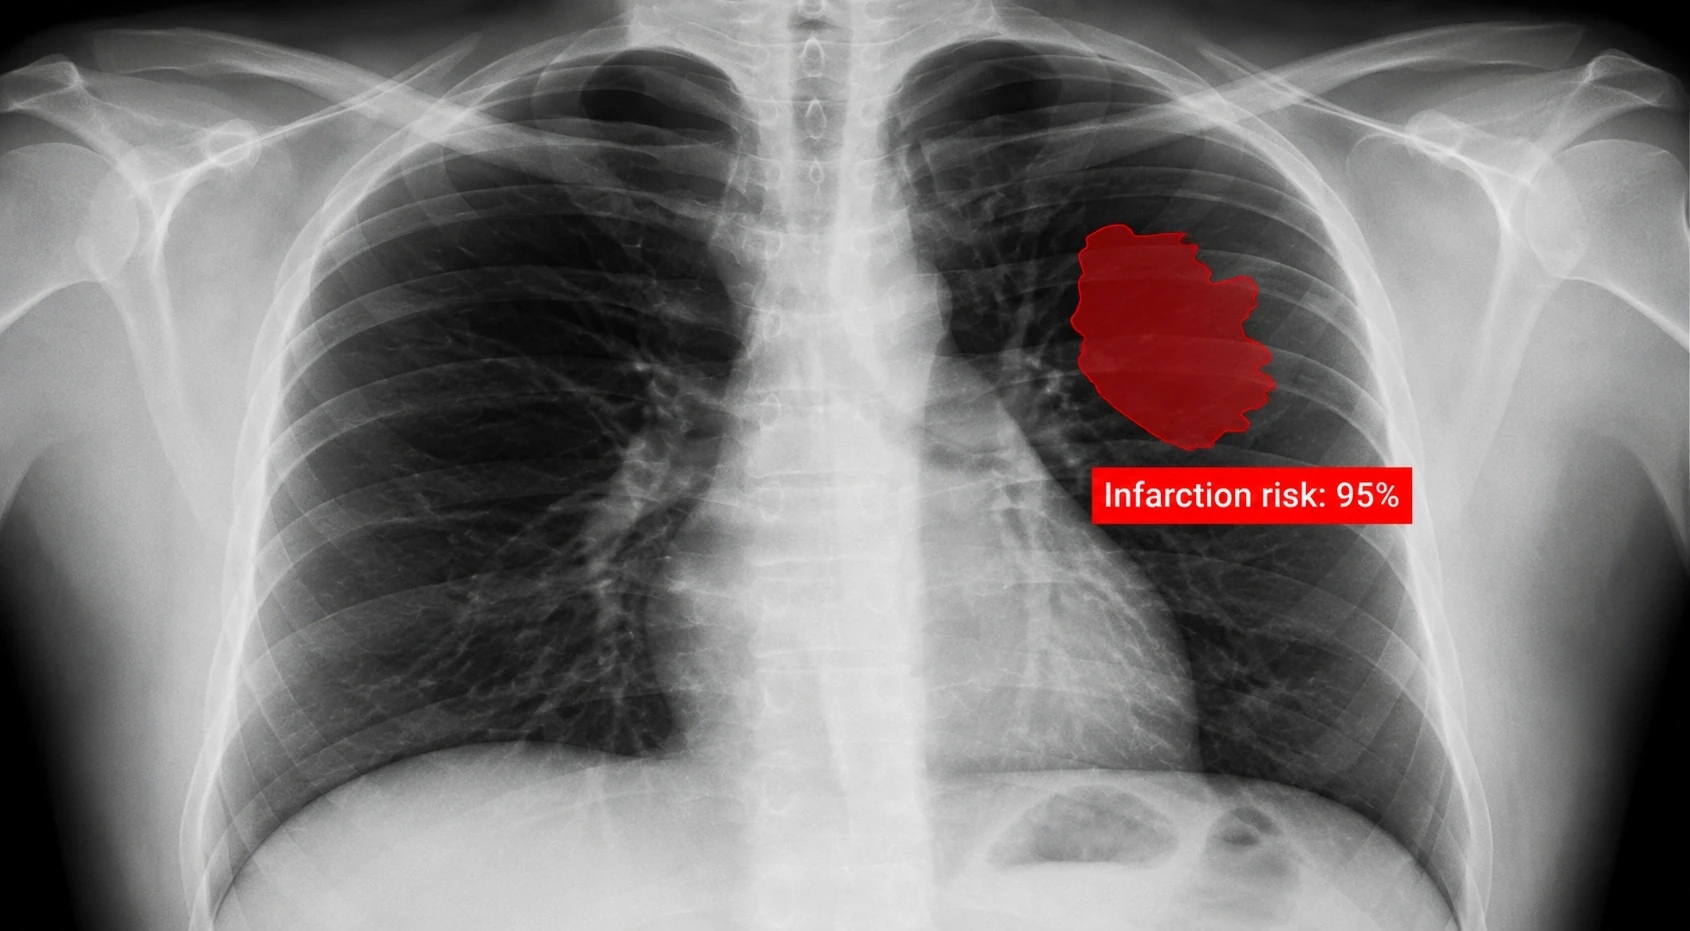
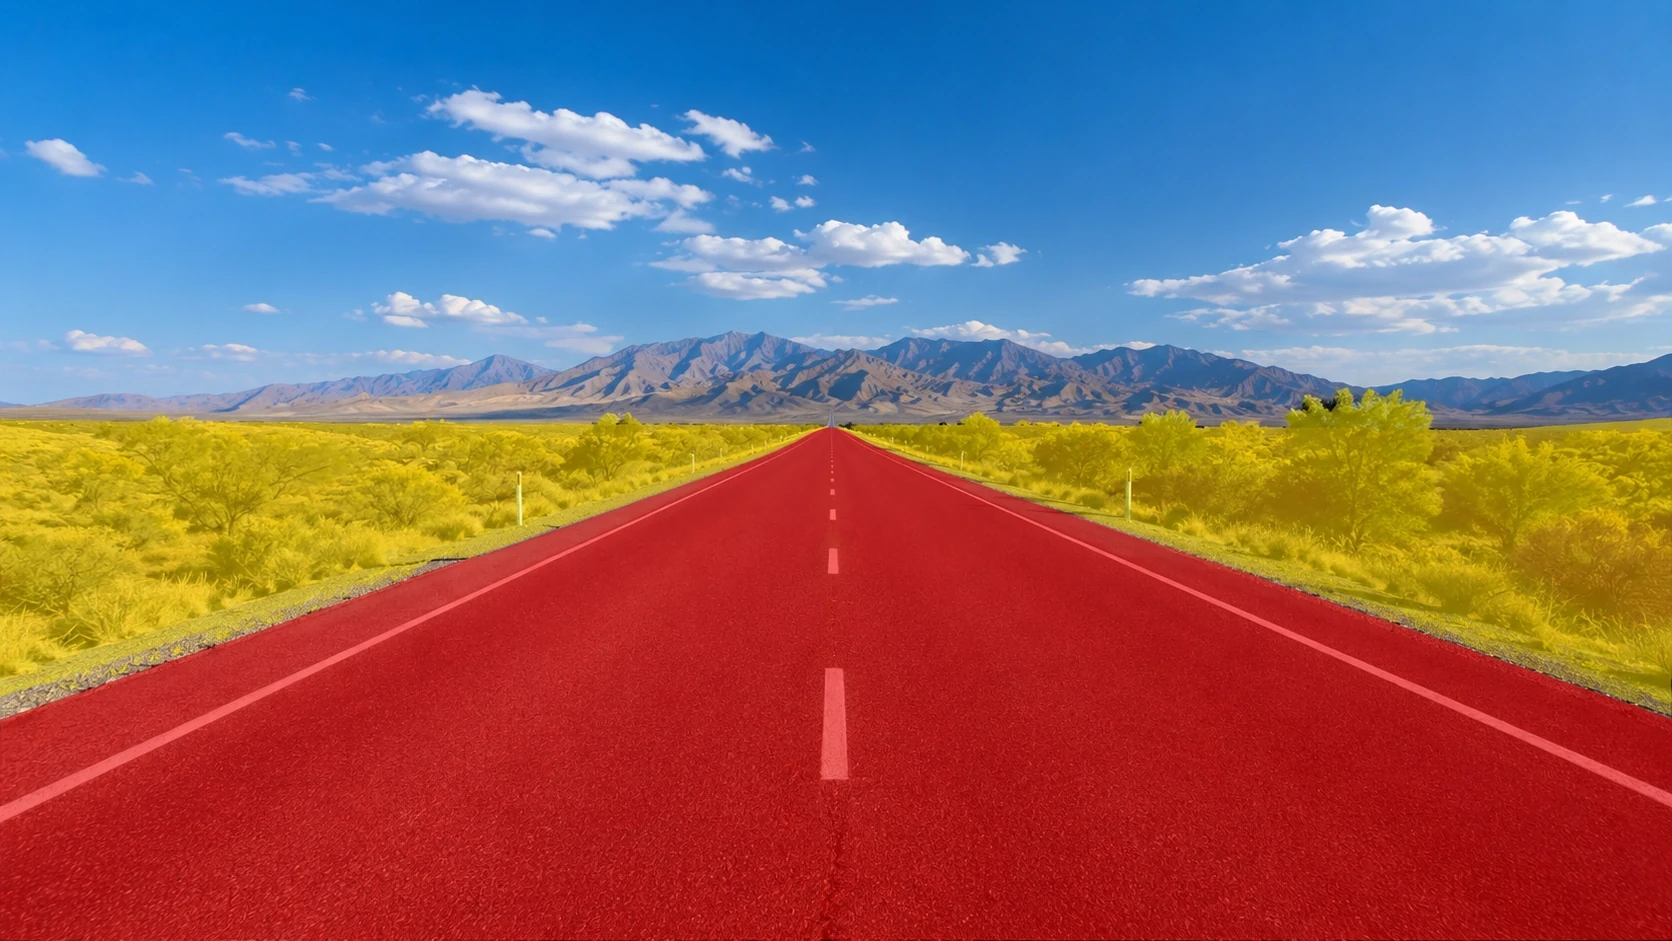
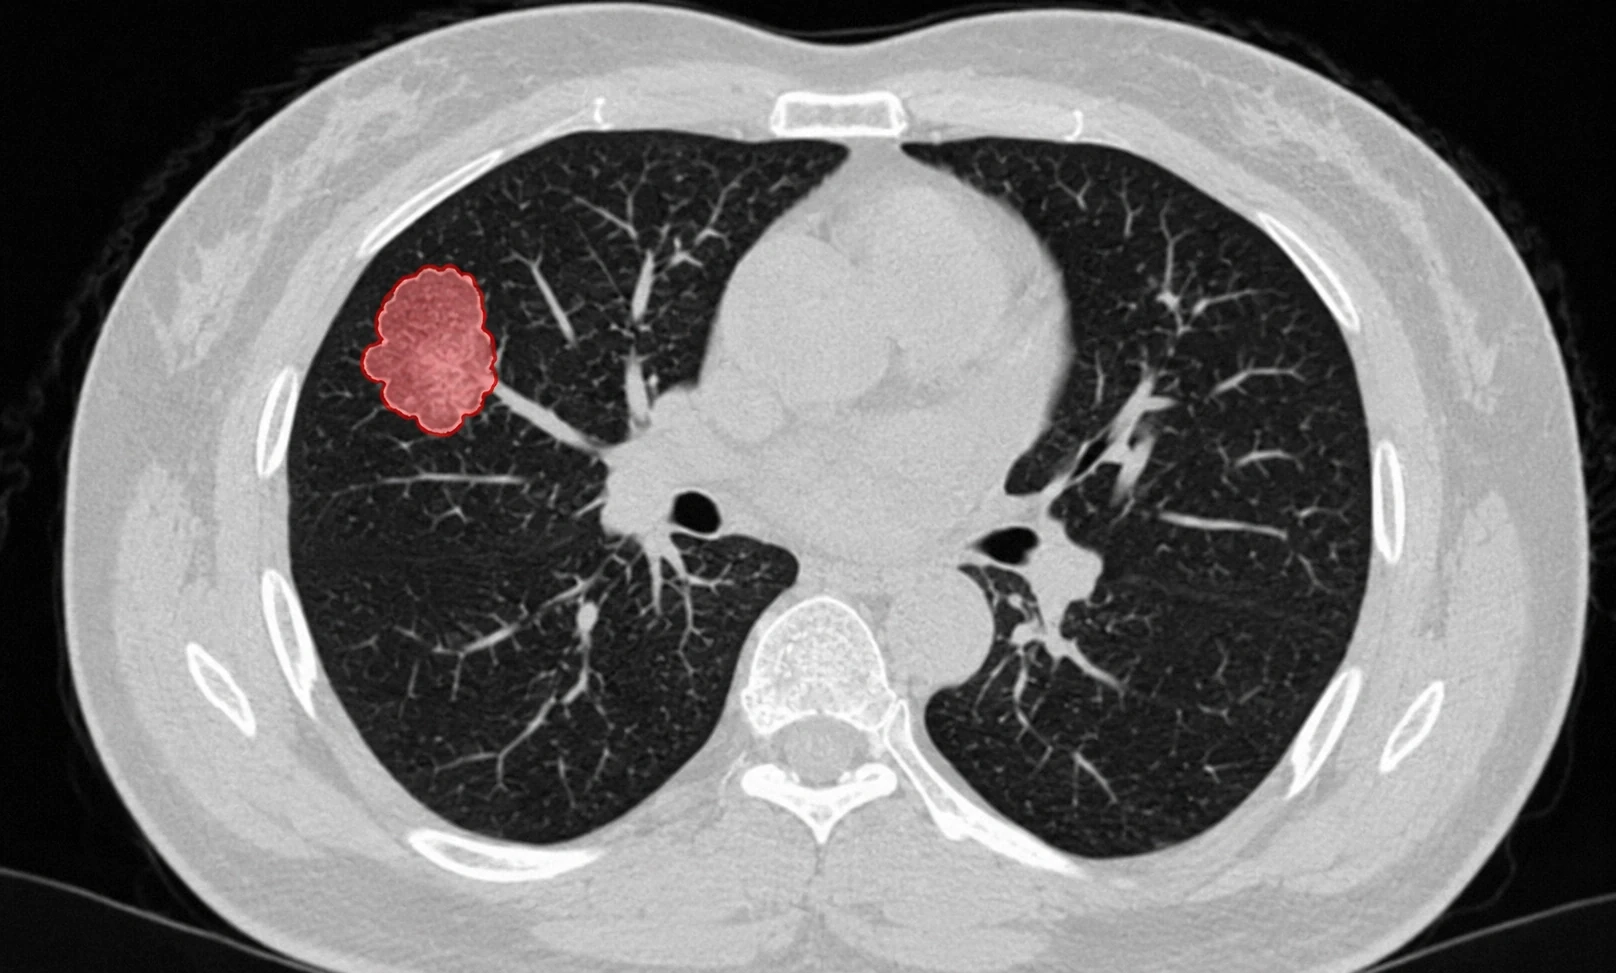
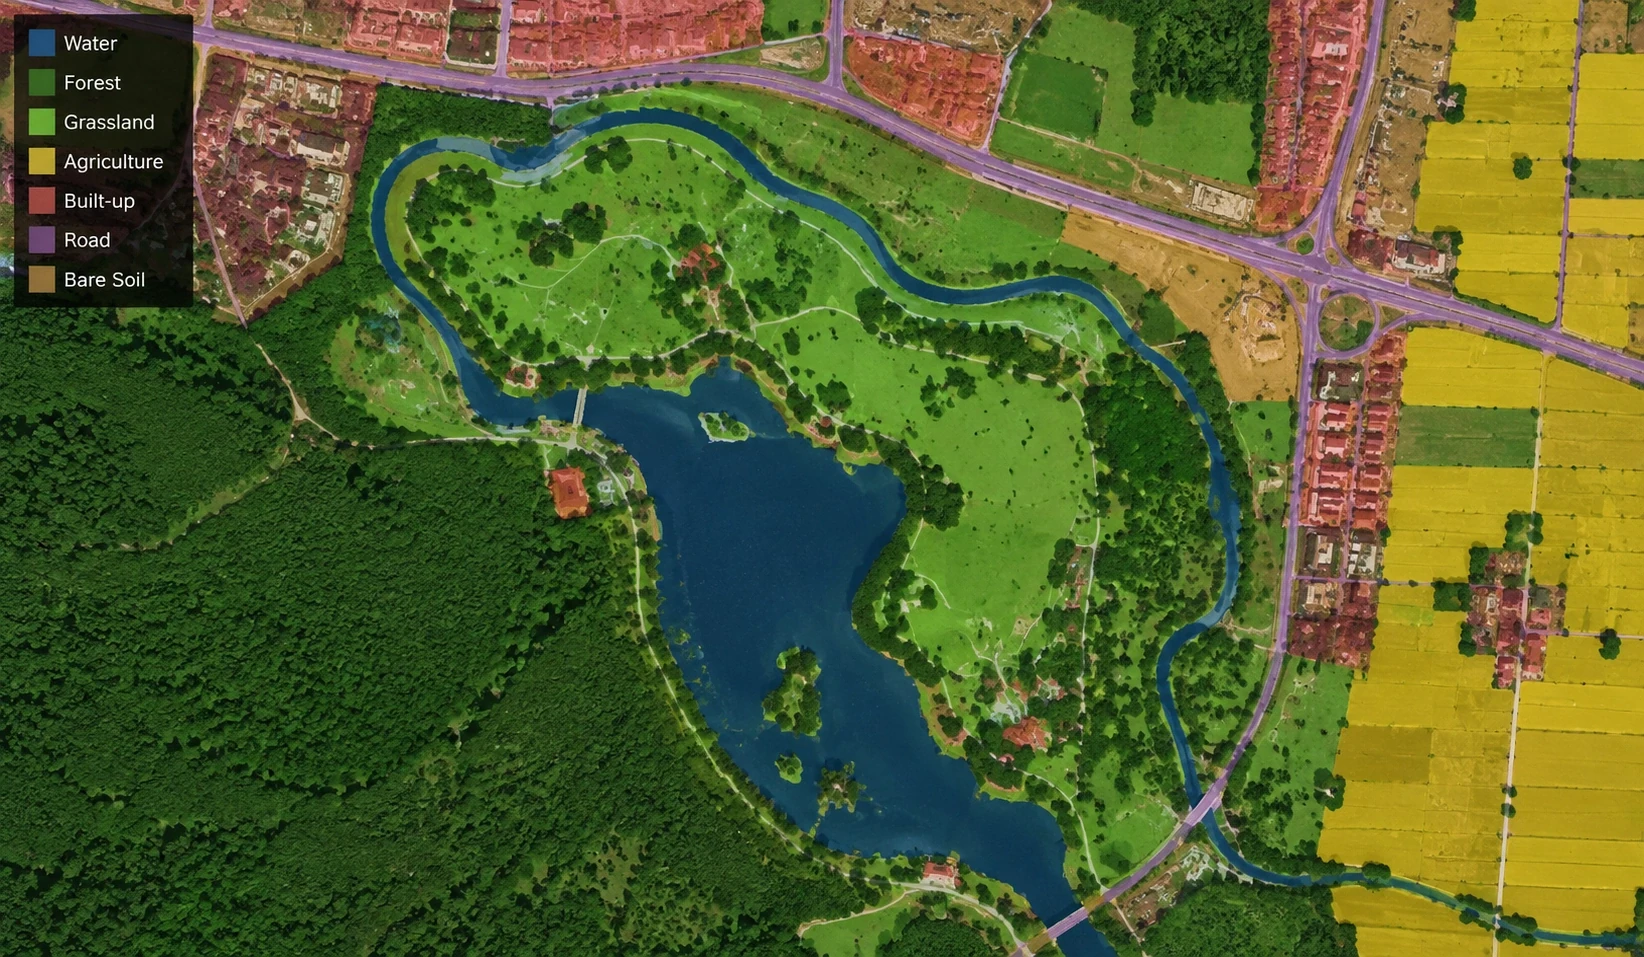
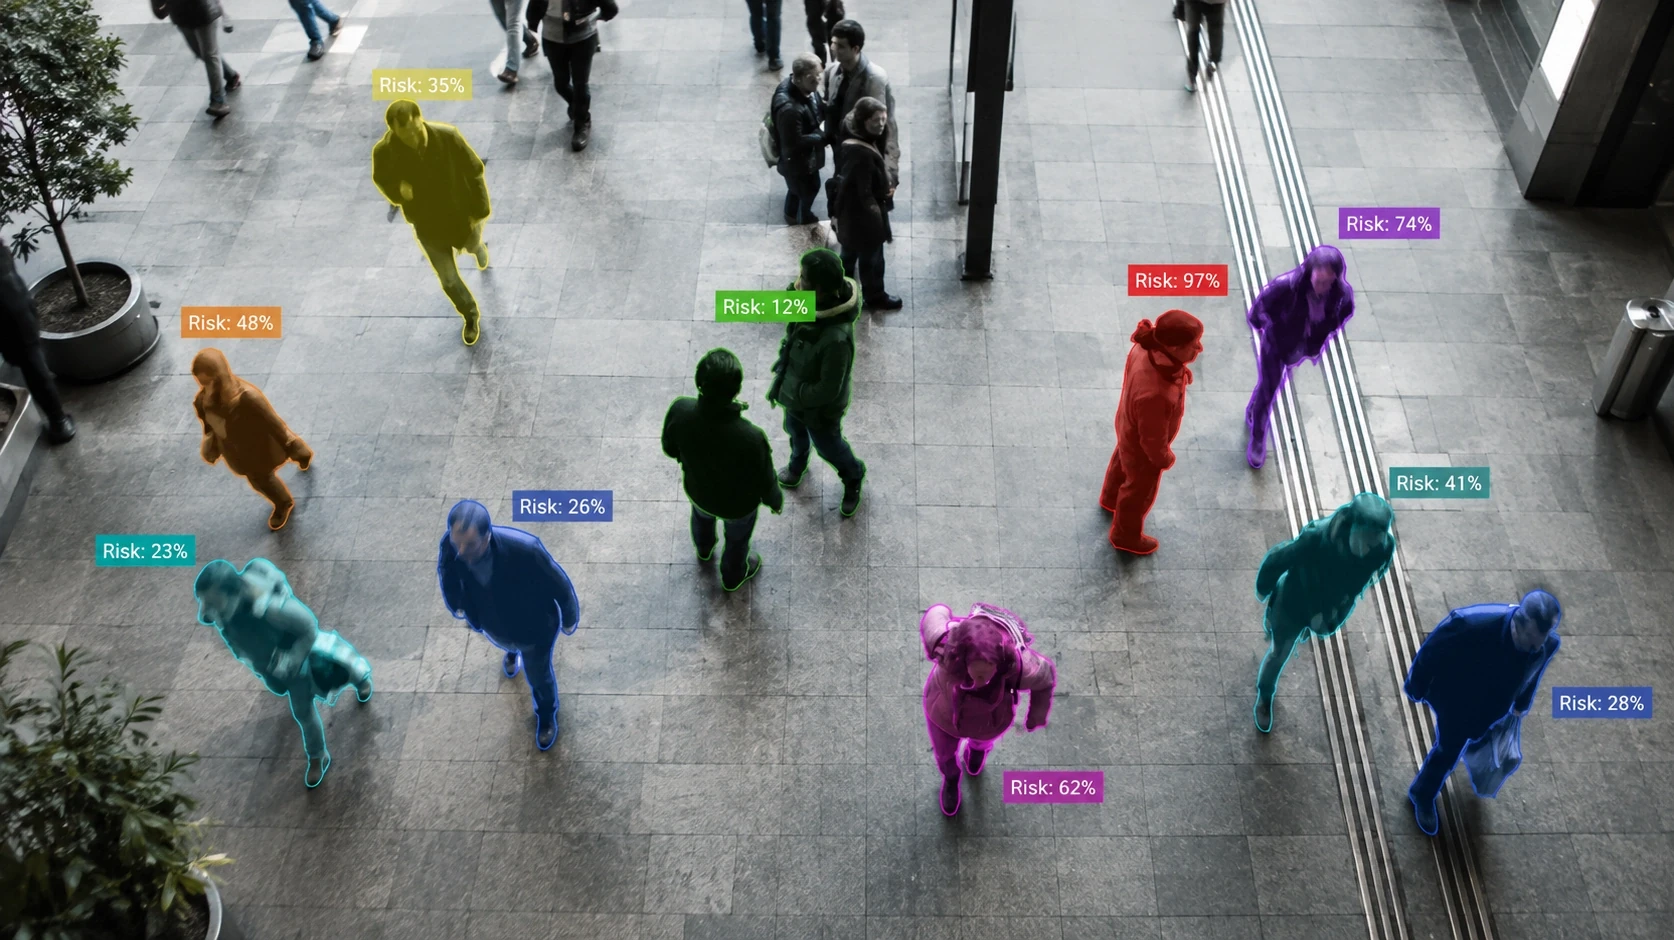
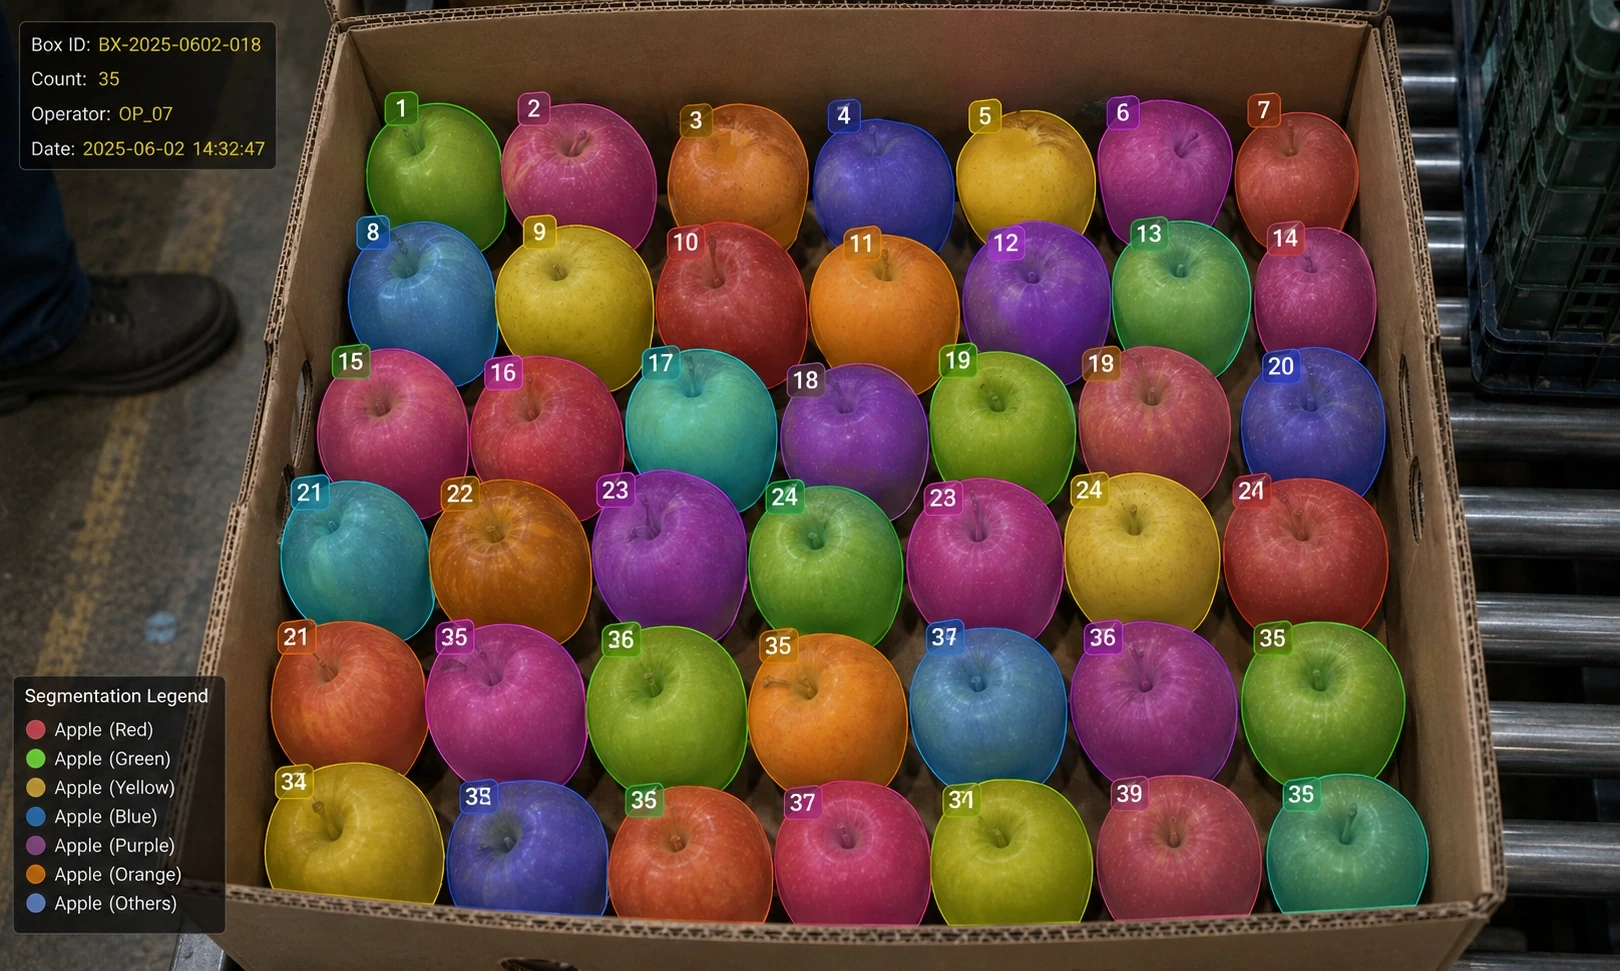
Bounding boxes, polygons, and semantic segmentation for rigorous computer vision models. High precision at industrial scale.
RUN FREE PILOT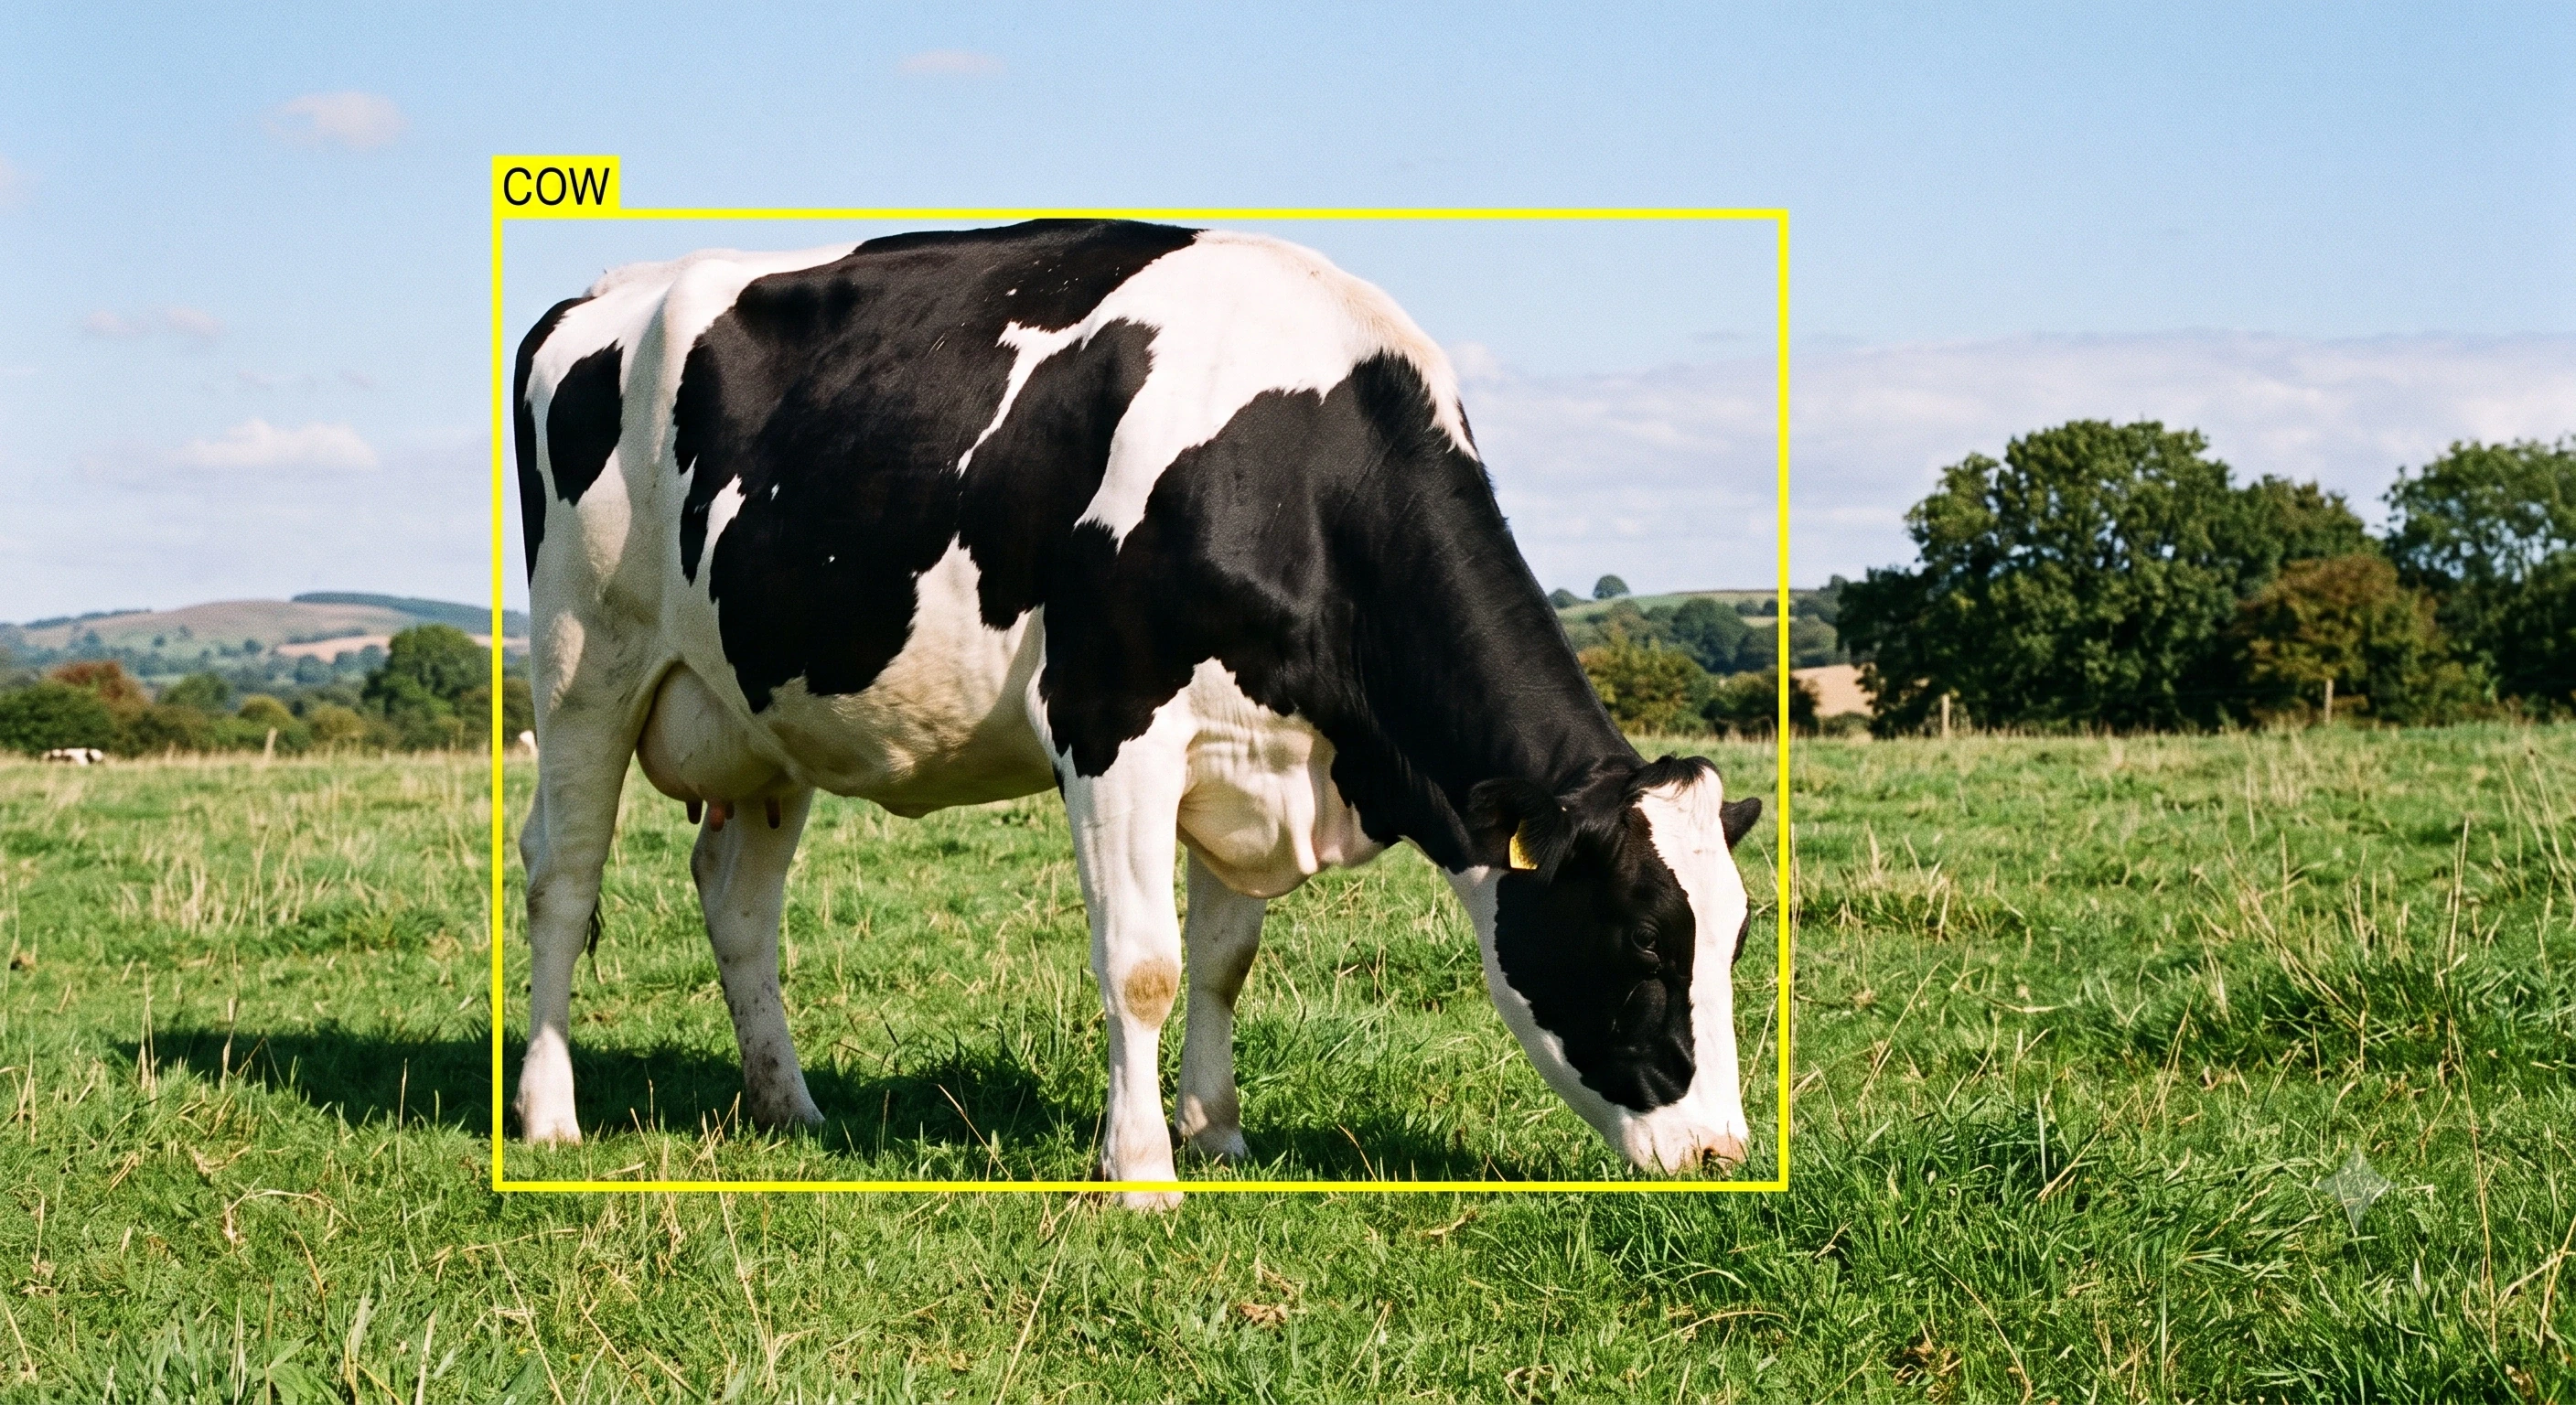
Trusted by leading brands

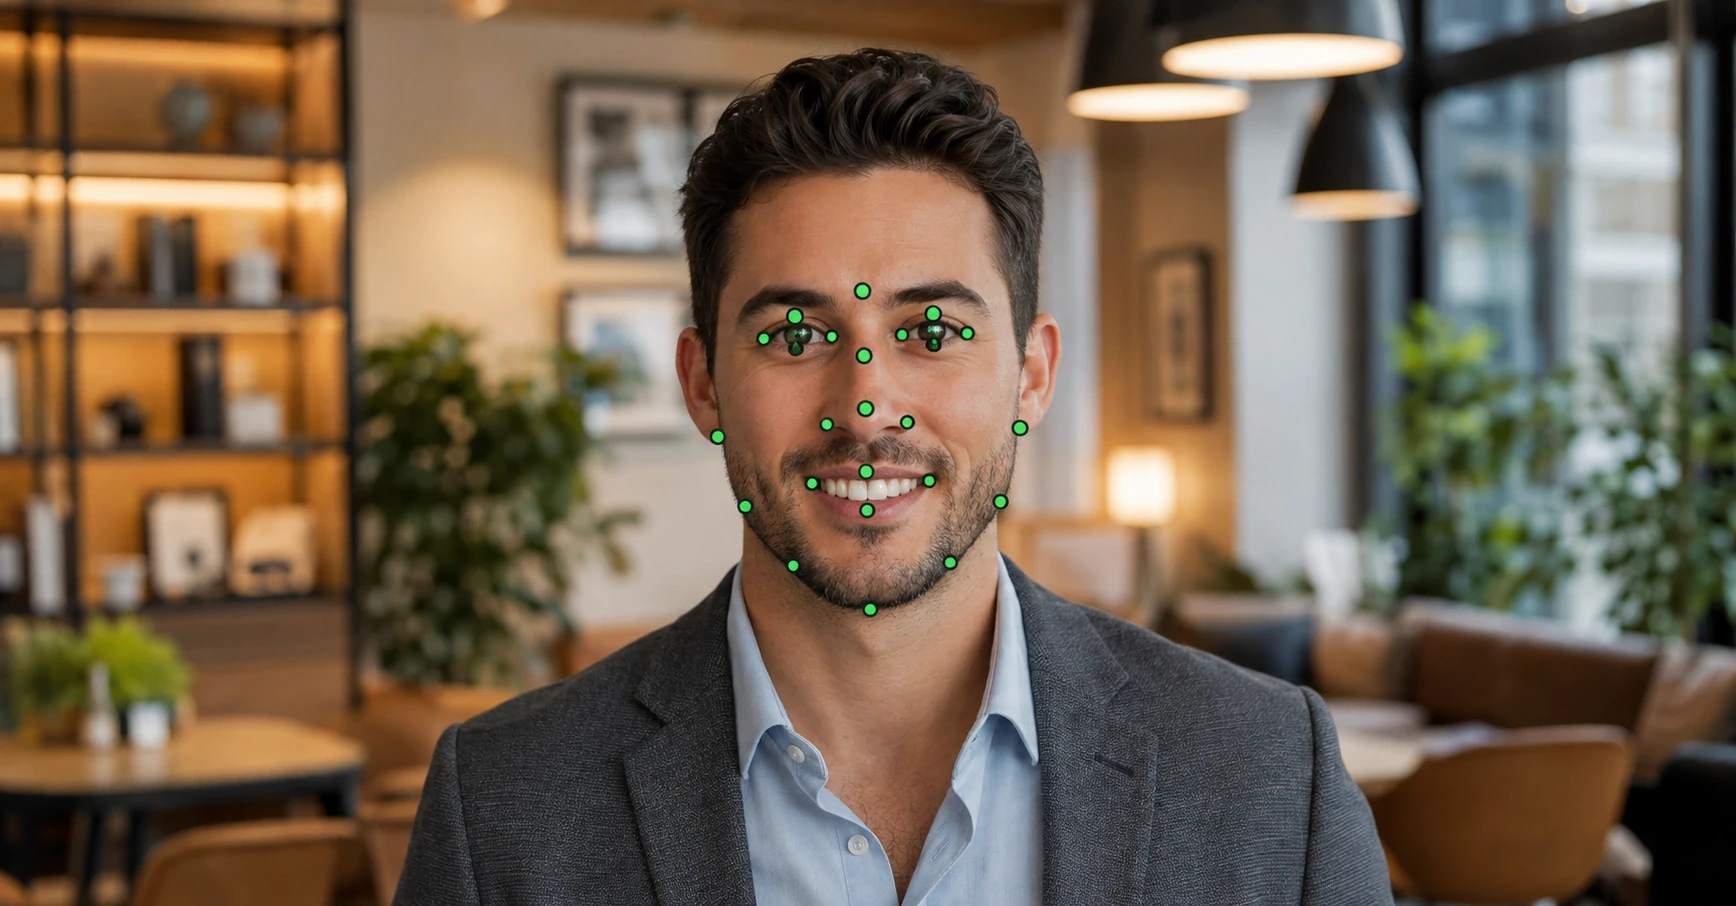
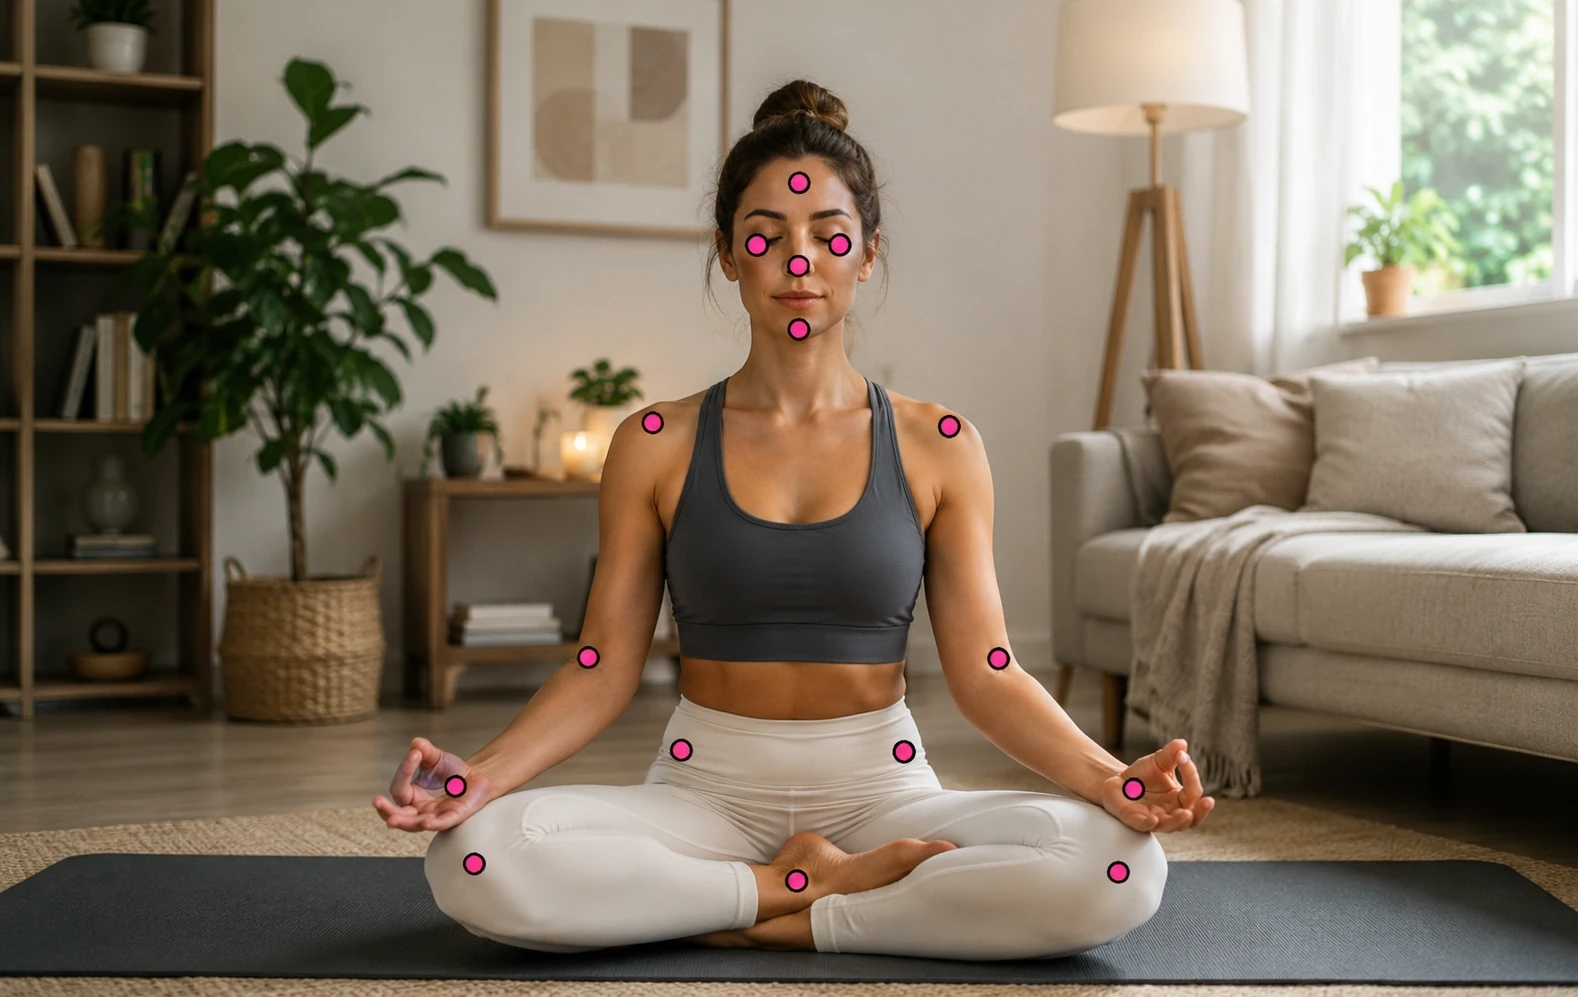
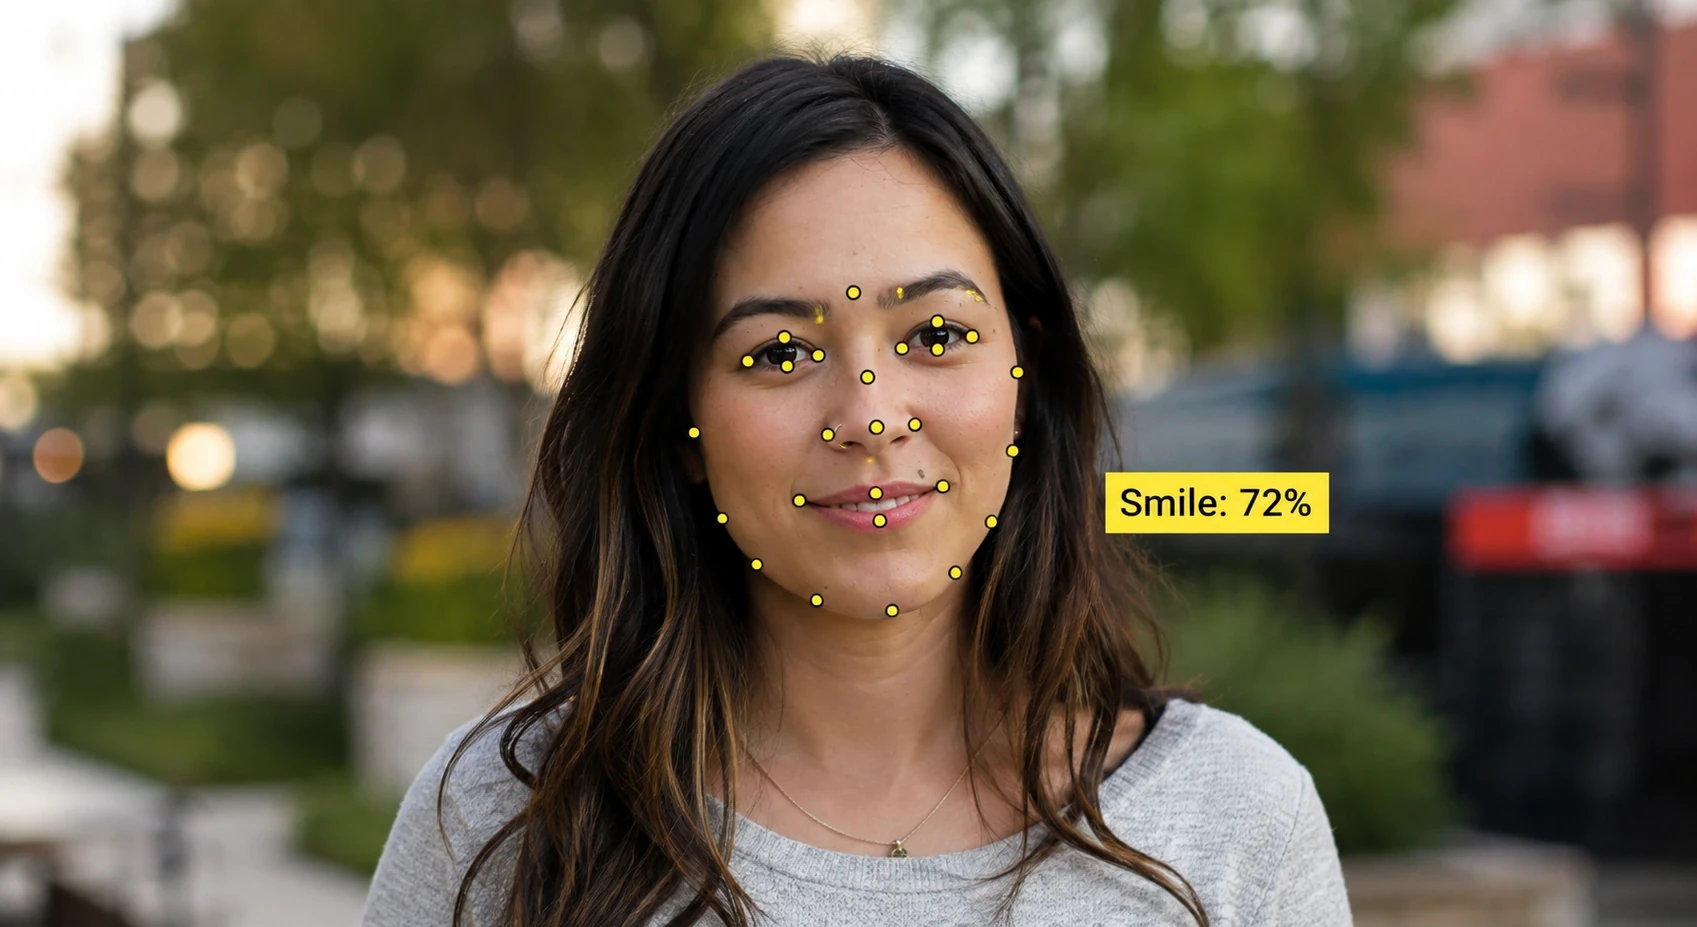
We provide high-precision annotation for all major computer vision tasks and datasets. Our global team can expertly deliver the following image annotation services:
Locating and classifying objects with tight bounding boxes for real-time AI perception.
We exist for a future where high-performance computer vision models are built on pristine, expertly annotated image data running perfectly within your infrastructure.
Clean, precise annotations feed your models exactly the ground truth they need — fewer errors, faster convergence.
Every annotation passes automated checks and senior human review before leaving our pipeline.
From pilot to production, we scale annotation capacity instantly while maintaining benchmark accuracy.
Your trust is our foundation. Engai is designed with a deep commitment to data privacy and security. Visit our trust page and security center to learn more.
fill up this form to send your pilot request
Discover how Engai's Data Pipeline and AI Infrastructure platform can make your organization AI-ready:
Automatically discover and map all datasets with contextualized inventory
Effortlessly manage ML lifecycle and address governance gaps
Drastically reduce deployment time by mitigating edge-case risks
Immediately detect and respond to model drift to minimize threat impact
Proactively apply zero-trust protection mechanisms for proprietary data
Your requirements and proprietary sample assets are encrypted in transit and never used for public model training.
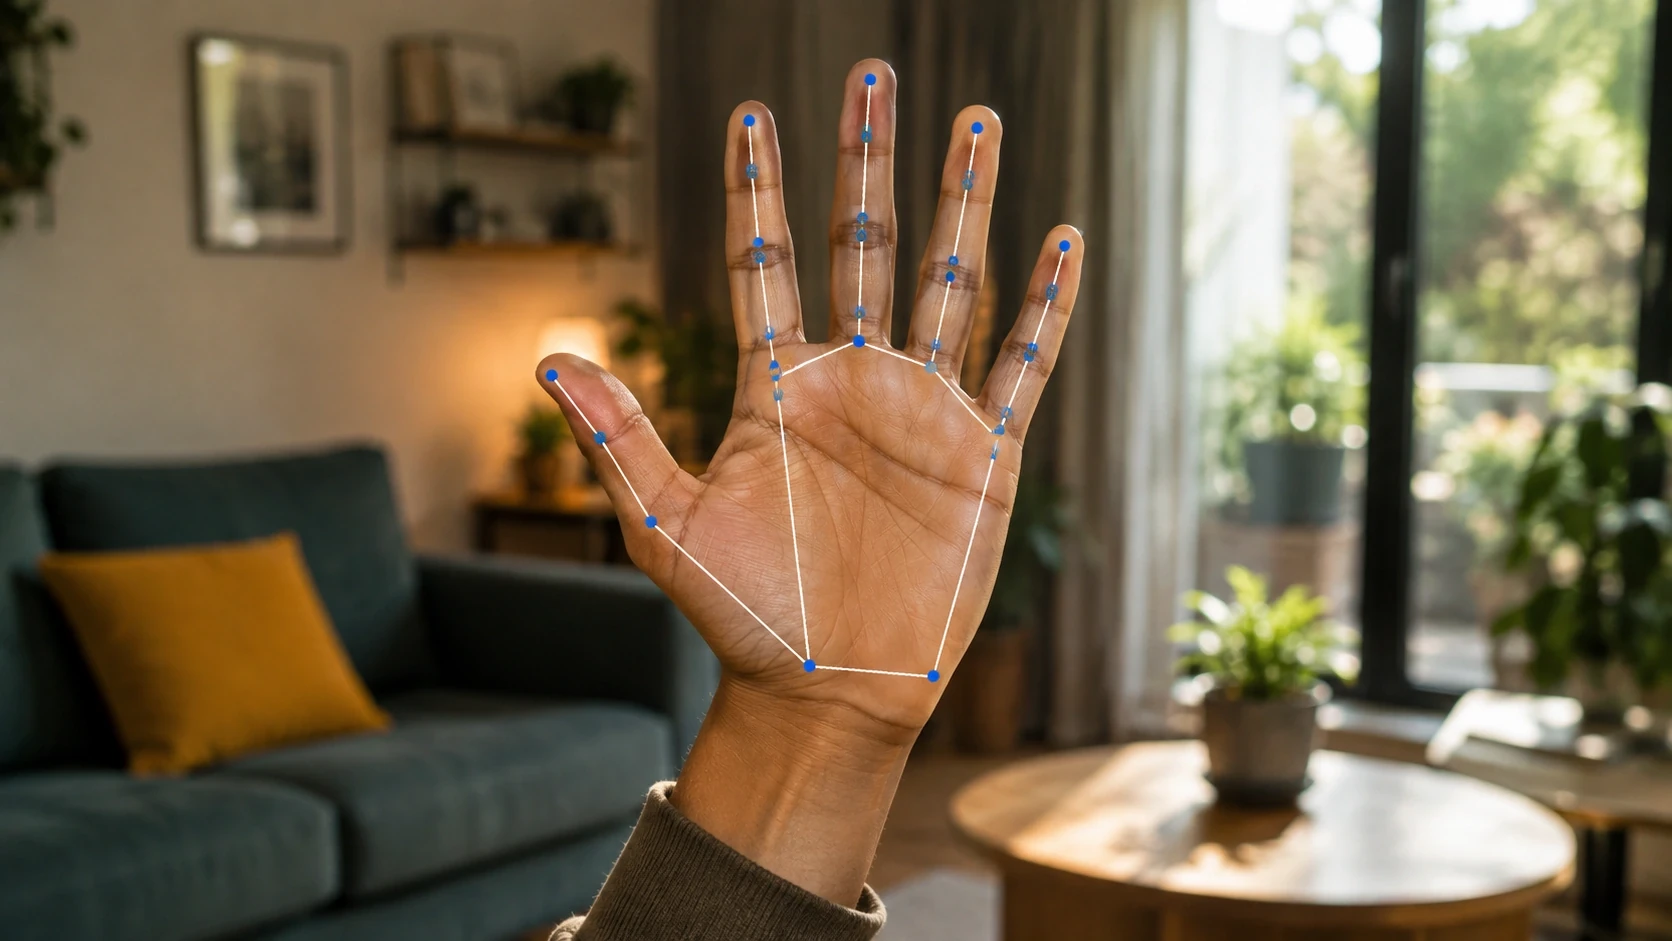
Engai provides a comprehensive range of image annotation services including bounding boxes, semantic and instance segmentation, polygon masks, keypoint detection, image classification, and 3D cuboid annotation. Our annotators are trained across all major vision task types for autonomous driving, medical imaging, retail, and more.